

Note
Go to the end to download the full example code or to run this example in your browser via Binder.
How do I adapt a pretrained EEG encoder with a linear probe?#
A shorter companion to the full fine-tuning example
(plot_73_finetune_pretrained_model.py). It adapts the published CBraMod
checkpoint to real HBN eyes-open/closed cues with the simplest transfer
strategy: freeze the pretrained encoder and train only a linear head on top.
The checkpoint is https://huggingface.co/braindecode/cbramod-pretrained
(documented by Braindecode’s CBraMod model). It was pretrained on TUH EEG;
this example uses the distinct HBN R5 mini cohort. It downloads about 20 MB
of weights and six challenge recordings in small mode (roughly 100 MB).
Opt in to full mode for eighteen recordings (roughly 320 MB).
Small mode uses three folds with two test, two reserved validation and two training participants. Full mode uses six folds with three test, three validation and twelve training participants. Each person is scored once per regime. Frozen embeddings are computed once; a train-only scaled logistic classifier provides the linear probe without a neural training loop. The small fixed budget demonstrates adaptation, not a foundation-model benchmark.
Before you start#
Use EEGDash, Braindecode, PyTorch, NumPy, scikit-learn and Matplotlib.
The public checkpoint requires network access on first use;
from_pretrained caches its weights separately from EEGDASH_CACHE_DIR,
which caches the selected EEG recordings. The revision below pins the actual
checkpoint rather than relying on a changing default branch.
The question here is narrow: does a frozen published representation, read out by a single linear layer, separate the two eye states in participants it has never seen? For the comparison with training from random weights and with full fine-tuning, see the full example. For the architecture and checkpoint contract, consult Braindecode’s pretrained-model example.
import matplotlib.pyplot as plt
import mne
import numpy as np
import pandas as pd
import torch
from braindecode.models import CBraMod
from braindecode.preprocessing import (
    Preprocessor,
    preprocess,
)
from sklearn.metrics import balanced_accuracy_score
from sklearn.linear_model import LogisticRegression
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

from eegdash.paths import get_default_cache_dir

from eegdash import EEGChallengeDataset
from eegdash.const import SUBJECT_MINI_RELEASE_MAP

CACHE_DIR = get_default_cache_dir()
RESOURCE_MODE = "small"  # explicit opt-in: "full" uses all 18 retained participants
N_FOLDS = 3 if RESOURCE_MODE == "small" else 6
N_VALID = 2 if RESOURCE_MODE == "small" else 3
torch.set_num_threads(2)
CHANNELS = ["E70", "E75", "E83"]  # three posterior (occipital) channels
SFREQ = 200  # CBraMod expects 200 Hz: one-second patches of 200 samples
# Steady-state window (start, stop) in seconds after each cue, as in the eyes-open/closed tutorial
CUE_WINDOW = {"instructed_toOpenEyes": (5, 19), "instructed_toCloseEyes": (15, 29)}
Match the real signal to the encoder input#
E70, E75 and E83 are an explicit small posterior-channel subset, not a claim that the complete HBN montage is interchangeable with the pretraining montage. The source challenge derivative has already been filtered and sampled at 100 Hz; resampling to 200 Hz satisfies CBraMod’s one-second, 200-sample patch contract but cannot recover information above the source Nyquist frequency.
Two of the twenty mini-release recordings have flat or saturated posterior electrodes (found by inspecting per-channel amplitudes) and are excluded by ID. Posterior amplitudes still differ by orders of magnitude across the remaining recordings, so each recording is standardized per channel with its own mean and standard deviation. That step uses no labels and is applied identically to every recording.
Windows sample the steady state of each eye condition rather than the instruction transient, following the eyes-open/closed tutorial: seven two-second windows from 5 to 19 s after an open-eyes cue (the open block lasts 20 s) and from 15 to 29 s after a close-eyes cue (the closed block lasts 40 s). The final open-eyes cue falls a few seconds before the recording ends and cannot supply the complete interval; MNE drops incomplete epochs. Labels represent the observed open/close instructions, not eye tracking.
# Load the resting-state recordings of the HBN R5 mini release, except two with
# flat or saturated posterior channels
BAD_RECORDINGS = ["NDARAP785CTE", "NDARCA740UC8"]
subjects = [
    s for s in sorted(SUBJECT_MINI_RELEASE_MAP["R5"]) if s not in BAD_RECORDINGS
]
if RESOURCE_MODE == "small":
    subjects = subjects[:6]  # about 100 MB; no outcome-based choice within this list
# Historical exclusions above are inherited, not reproduced by a QC threshold.
# They limit the estimand to this selected cohort; do not call it representative.
dataset = EEGChallengeDataset(
    release="R5", mini=True, task="RestingState", subject=subjects, cache_dir=CACHE_DIR
)


def standardize_recording(x):
    """Offline whole-recording normalization, including the held-out recording."""
    scale = x.std(axis=1, keepdims=True)
    return (x - x.mean(axis=1, keepdims=True)) / scale


preprocess(
    dataset,
    [
        Preprocessor("pick", picks=CHANNELS),
        Preprocessor("resample", sfreq=SFREQ),
        # standardize each channel of each recording with its own mean and std (uses no labels)
        Preprocessor(standardize_recording),
    ],
)

# Cut seven 2 s epochs per eligible cue with explicit MNE sample origins.
# Native epochs reject BAD spans and incomplete trailing windows.
# Cue-specific offsets below avoid discarding valid open-eye windows based
# on the longer closed-eye interval.
epoch_arrays, metadata_tables = [], []
for recording in dataset.datasets:
    raw = recording.raw
    events = []
    for annotation in raw.annotations:
        cue = annotation["description"]
        if cue not in CUE_WINDOW:
            continue
        start, stop = CUE_WINDOW[cue]
        onset = annotation["onset"] - raw.first_time
        code = 1 if cue == "instructed_toOpenEyes" else 2
        for offset in range(start, stop, 2):
            sample = round((onset + offset) * SFREQ) + raw.first_samp
            events.append([sample, 0, code])
    events = np.asarray(events)
    epochs = mne.Epochs(
        raw,
        events[np.argsort(events[:, 0])],
        event_id={"eyes_open": 1, "eyes_closed": 2},
        tmin=0,
        tmax=2 - 1 / SFREQ,
        baseline=None,
        preload=True,
        reject_by_annotation=True,
    )
    epoch_arrays.append(epochs.get_data())
    metadata_tables.append(
        pd.DataFrame(
            {
                "target": epochs.events[:, 2] - 1,
                "subject": str(recording.description["subject"]),
            }
        )
    )
╭────────────────────── EEG 2025 Competition Data Notice ──────────────────────╮
│ This object loads the HBN dataset that has been preprocessed for the EEG     │
│ Challenge:                                                                   │
│   * Downsampled from 500Hz to 100Hz                                          │
│   * Bandpass filtered (0.5-50 Hz)                                            │
│                                                                              │
│ For full preprocessing applied for competition details, see:                 │
│   https://github.com/eeg2025/downsample-datasets                             │
│                                                                              │
│ The HBN dataset have some preprocessing applied by the HBN team:             │
│   * Re-reference (Cz Channel)                                                │
│                                                                              │
│ IMPORTANT: The data accessed via `EEGChallengeDataset` is NOT identical to   │
│ what you get from EEGDashDataset directly.                                   │
│ If you are participating in the competition, always use                      │
│ `EEGChallengeDataset` to ensure consistency with the challenge data.         │
╰──────────────────────── Source: EEGChallengeDataset ─────────────────────────╯
[10/09/26 23:14:47] INFO     Auto-corrected misrouted             dataset.py:561
                             storage.base for dataset
                             EEG2025r5mini: None ->
                             s3://nemar/EEG2025r5mini
/home/runner/work/EEGDash/EEGDash/.venv/lib/python3.12/site-packages/braindecode/preprocessing/preprocess.py:78: UserWarning: apply_on_array can only be True if fn is a callable function. Automatically correcting to apply_on_array=False.
  warn(
/home/runner/work/EEGDash/EEGDash/examples/tutorials/70_transfer_foundation/plot_73_finetune_pretrained_model_simple.py:143: RuntimeWarning: 7 events are outside the data range; the corresponding epochs cannot be created. This can happen if the events were created at a different sampling frequency, or have entries before first_samp.
  epochs = mne.Epochs(
Not setting metadata
77 matching events found
No baseline correction applied
0 projection items activated
Using data from preloaded Raw for 77 events and 400 original time points ...
7 bad epochs dropped
/home/runner/work/EEGDash/EEGDash/examples/tutorials/70_transfer_foundation/plot_73_finetune_pretrained_model_simple.py:143: RuntimeWarning: 6 events are outside the data range; the corresponding epochs cannot be created. This can happen if the events were created at a different sampling frequency, or have entries before first_samp.
  epochs = mne.Epochs(
Not setting metadata
77 matching events found
No baseline correction applied
0 projection items activated
Using data from preloaded Raw for 77 events and 400 original time points ...
7 bad epochs dropped
/home/runner/work/EEGDash/EEGDash/examples/tutorials/70_transfer_foundation/plot_73_finetune_pretrained_model_simple.py:143: RuntimeWarning: 7 events are outside the data range; the corresponding epochs cannot be created. This can happen if the events were created at a different sampling frequency, or have entries before first_samp.
  epochs = mne.Epochs(
Not setting metadata
77 matching events found
No baseline correction applied
0 projection items activated
Using data from preloaded Raw for 77 events and 400 original time points ...
7 bad epochs dropped
/home/runner/work/EEGDash/EEGDash/examples/tutorials/70_transfer_foundation/plot_73_finetune_pretrained_model_simple.py:143: RuntimeWarning: 6 events are outside the data range; the corresponding epochs cannot be created. This can happen if the events were created at a different sampling frequency, or have entries before first_samp.
  epochs = mne.Epochs(
Not setting metadata
77 matching events found
No baseline correction applied
0 projection items activated
Using data from preloaded Raw for 77 events and 400 original time points ...
7 bad epochs dropped
Reserve participants, not windows#
X has shape (windows, 3, 400) and y contains the two integer
instruction classes. Participants, rather than windows, determine the folds:
group-disjoint folds use the counts in the parameter cell. Each participant
is tested exactly once per regime, regardless of resource mode.
The classifier setting is fixed before fitting. Validation people are reserved for later development; test labels only score the final predictions.
# Arrays for PyTorch: X = (windows, channels, samples), y = label, subject = participant of each window
X = np.concatenate(epoch_arrays).astype("float32")
metadata = pd.concat(metadata_tables, ignore_index=True)
y = metadata["target"].to_numpy()
subject = metadata["subject"].to_numpy()
print(f"X {X.shape} | classes {np.bincount(y)} | participants {len(subjects)}")

# Every participant is tested exactly once, in either resource mode
folds = np.array_split(np.array(subjects), N_FOLDS)
# Full-recording normalization uses each test recording's unlabeled distribution:
# this is offline/transductive preprocessing, not causal online deployment.
X (420, 3, 400) | classes [210 210] | participants 6
Load the checkpoint and understand the head dimensions#
return_encoder_output=True exposes CBraMod’s patch representations.
For three channels and two one-second patches, each with 200 representation
coordinates, flattening gives 3 × 2 × 200 = 1200 inputs to the two-class
linear head. These fixed coordinates feed a logistic classifier below.
Its learned coefficients are the linear readout.
If you change channels or duration, derive the new head width from a real
encoder forward pass. Merely changing n_outputs cannot fix a mismatched
feature shape. The same principle is illustrated in Braindecode’s
foundation-model fine-tuning walkthrough.
# Download the published checkpoint (about 20 MB); the revision pins the exact weights
pretrained = CBraMod.from_pretrained(
    "braindecode/cbramod-pretrained",
    revision="584cdc415913739a05d84bf0c1cb3db397764507",
    return_encoder_output=True,  # return the patch features instead of class scores
    n_chans=len(CHANNELS),
    n_times=2 * SFREQ,
    sfreq=SFREQ,
)
Cache frozen representations in memory once#
Evaluation mode disables dropout. This fixed transform sees no labels and learns no cohort statistics. The scaler is fitted only on training people. C=1 is prespecified; validation people remain available for later development but are not used to choose a setting in this compact example.
pretrained.eval().requires_grad_(False)
with torch.inference_mode():
    embeddings = np.concatenate(
        [
            pretrained(batch).flatten(1).numpy()
            for batch in torch.from_numpy(X).split(16)
        ]
    )
print("Frozen feature matrix:", embeddings.shape)
scores = []
for test_subjects in folds:
    others = [s for s in subjects if s not in test_subjects]
    train = np.isin(subject, others[:-N_VALID])
    test = np.isin(subject, test_subjects)
    model = make_pipeline(StandardScaler(), LogisticRegression(C=1, max_iter=1000))
    model.fit(embeddings[train], y[train])
    pred = model.predict(embeddings[test])
    for identity in test_subjects:
        mask = subject[test] == identity
        scores.append(balanced_accuracy_score(y[test][mask], pred[mask]))
    print("Held out:", test_subjects, "scores:", scores[-len(test_subjects) :])
Frozen feature matrix: (420, 1200)
Held out: ['NDARAH793FBF' 'NDARAJ689BVN'] scores: [0.5, 0.5]
Held out: ['NDARAU708TL8' 'NDARBE091BGD'] scores: [0.6714285714285715, 0.6571428571428571]
Held out: ['NDARBE103DHM' 'NDARBF851NH6'] scores: [0.7285714285714286, 0.6857142857142857]
Plot one score per participant#
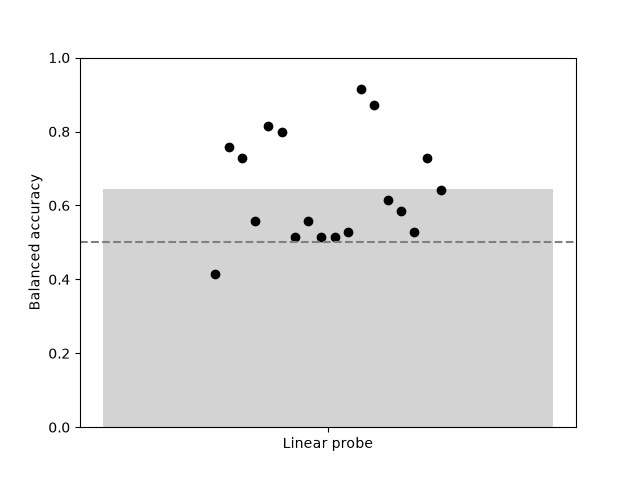
Each dot is one held-out participant; the bar is the mean over the selected participants and the dashed line is the two-class chance level.
plt.bar(0, np.mean(scores), color="lightgray")
plt.scatter(np.linspace(-0.2, 0.2, len(scores)), scores, color="k")
plt.axhline(0.5, ls="--", color="gray")
plt.ylim(0, 1)
plt.ylabel("Balanced accuracy")
plt.xticks([0], ["Linear probe"])
plt.show()
Read the result and design the next experiment#
The measured dots may lie above or below chance. This page does not measure alpha reactivity or establish that pretraining caused a gain. The full page compares regimes descriptively on paired participants; overlapping training folds and one seed do not justify an independent-pairs significance test. This fixed logistic probe is not identical to the full page’s AdamW probe.
To extend this page, unfreeze the encoder with a smaller learning rate (fine-tuning), add repeated seeds, and prespecify longer budgets. Save the selected weights together with the checkpoint revision, channel order, rate, window offsets, standardization rule and subject lists if you reuse the trained model; weights alone omit the input contract.
Total running time of the script: (0 minutes 2.716 seconds)