

Note
Go to the end to download the full example code or to run this example in your browser via Binder.
Eyes-open versus eyes-closed decoding on a cluster#
Load actual HBN ds005514 RestingState recordings with EEGDashDataset,
reannotate observed open/close instructions, and train a neural classifier.
The default selects three explicit, previously inspected subject IDs;
all selected subjects must load successfully. The three signal files total
281.2 MB plus sidecars. See HBN ds005514. Inspect sizes before staging.
This is a full EO/EC workload, not the small real-data CI smoke test.
From the repository root, submit sbatch examples/hpc/run_eoec_cpu.slurm
after configuring the cluster account/partition and Python environment.
Use EEGDASH_CACHE_DIR for persistent or pre-staged node-local cache,
NUM_SUBJECTS=3, NUM_TEST_SUBJECTS=1 and SEED=42 by default.
The test subjects remain untouched until the fixed training schedule ends.
The single split is a workflow demonstration, not a population benchmark.
Prerequisites: tutorial 02’s DataLoader, tutorial 11’s subject split and
basic PyTorch training. Install the project dependencies, including a
PyTorch build appropriate for the compute node, plus EEGPrep and its
EEGLAB reader (pip install 'eegprep[eeglabio]>=0.2.23,<0.3'). A CPU can run the default
cohort; the GPU Slurm template requests a GPU but training selects CUDA only
when PyTorch can access one. Cluster accounts and partitions are site-specific.
The deliverables are a labelled voltage plot, training history and metrics in a unique run directory under EEGDASH_OUTPUT_DIR (default: cache/hpc-runs). The script does not save a reusable trained model; write model state and the preprocessing/subject configuration explicitly if a later inference job needs them.
from pathlib import Path
import os
import json
import tempfile
from time import perf_counter

import pandas as pd

import numpy as np
import torch


from eegdash import EEGDashDataset
from eegdash.paths import get_default_cache_dir
from braindecode.preprocessing import (
    preprocess,
    Preprocessor,
    RemoveDCOffset,
    RemoveDrifts,
    Resampling,
    create_windows_from_events,
)
from eegdash.hbn.preprocessing import hbn_ec_ec_reannotation
1. Configure the bounded real-data workload#
cache_folder = get_default_cache_dir()
cache_folder.mkdir(parents=True, exist_ok=True)
dataset_id = "ds005514"
task = "RestingState"

# Explicit upper bound; failed acquisitions stop the job.
num_subjects = int(os.environ.get("NUM_SUBJECTS", "3"))
num_test_subjects = int(os.environ.get("NUM_TEST_SUBJECTS", "1"))
random_state = int(os.environ.get("SEED", "42"))

# 2 seconds at 128 Hz
window_size_samples = 256

# training params
epochs = int(os.environ.get("EPOCHS", "6"))
batch_size = int(os.environ.get("BATCH_SIZE", "32"))
allocated_cpus = int(os.environ.get("SLURM_CPUS_PER_TASK", "1"))
torch.set_num_threads(allocated_cpus)
offline_value = os.environ.get("EEGDASH_OFFLINE", "0")
download = offline_value == "0"
output_root = Path(os.environ.get("EEGDASH_OUTPUT_DIR", str(cache_folder / "hpc-runs")))
output_root = output_root.expanduser().resolve()
output_root.mkdir(parents=True, exist_ok=True)
# Exclusive creation gives concurrent/requeued jobs distinct destinations.
run_dir = Path(tempfile.mkdtemp(prefix="eoec-", dir=output_root))
print("Run output (preserved on failure):", run_dir)
run_start = perf_counter()
Run output (preserved on failure): /home/runner/eegdash_cache/hpc-runs/eoec-3_kny6ik
2. Define preprocessing and observed-instruction reannotation#
The HBN-specific preprocessor derives windows from recorded instructions. For eyes-closed it starts two-second segments 15–27 seconds after the close cue; for eyes-open it starts them 5–17 seconds after the open cue. This avoids immediate cue transitions. The labels indicate instructed state rather than an independent measurement that a participant complied.
We keep a fixed 24-channel montage subset so the neural model sees identical sensor ordering. EEGPrep RemoveDCOffset subtracts the per-channel median; RemoveDrifts applies a fixed forward/backward high-pass transition from 0.5 to 1 Hz. EEGPrep Resampling reduces the rate to 128 Hz with anti-aliasing. A final 55 Hz low-pass avoids frequencies near the new 64 Hz Nyquist limit. These deterministic per-recording operations use no population-fitted state. These resampling components preserve duration; restore the original instruction times after conversion through EEGPrep. Reannotation then creates state markers on the resampled grid. This is component-level EEGPrep preprocessing, not automatic ASR/artifact rejection.
channels = (
    "E22 E9 E33 E24 E11 E124 E122 E29 E6 E111 E45 E36 "
    "E104 E108 E42 E55 E93 E58 E52 E62 E92 E96 E70 Cz"
).split()

preprocessors = [
    Preprocessor("pick", picks=channels),
    Preprocessor("reorder_channels", ch_names=channels),
    RemoveDCOffset(),
    RemoveDrifts(transition=(0.5, 1.0)),
    Resampling(sfreq=128),
    Preprocessor("filter", l_freq=None, h_freq=55),
]
/home/runner/work/EEGDash/EEGDash/.venv/lib/python3.12/site-packages/braindecode/preprocessing/preprocess.py:78: UserWarning: apply_on_array can only be True if fn is a callable function. Automatically correcting to apply_on_array=False.
  warn(
3. Load the selected participants and create real EO/EC windows#
SUBJECTS is an explicit comma-separated cohort. NUM_SUBJECTS selects a prefix of that list and must not exceed it. Increase both settings when adding participants; the script never searches for replacements after an error. The default subjects were inspected for both instruction labels and the requested channel names. Inspect those contracts again for a new cohort.
subjects_all = os.environ.get(
    "SUBJECTS", "NDARAE710YWG,NDARAH239PGG,NDARAL897CYV"
).split(",")
subjects_all = [subject.strip() for subject in subjects_all]

all_windows = []
all_subject_ids = []
valid_subjects = []

if not 2 <= num_subjects <= len(subjects_all):
    raise ValueError("NUM_SUBJECTS must select at least two IDs from SUBJECTS.")
if not 1 <= num_test_subjects < num_subjects:
    raise ValueError("Reserve at least one training and one test participant.")
selected_subjects = subjects_all[:num_subjects]
print("Selected subjects:", selected_subjects)
for subj in selected_subjects:
    ds_eoec = EEGDashDataset(
        dataset=dataset_id,
        task=task,
        subject=subj,
        cache_dir=cache_folder,
        download=download,
        n_jobs=1,
    )
    original_annotations = []
    for recording in ds_eoec.datasets:
        raw = recording.raw
        # The current HBN reannotation helper assumes a zero sample origin.
        if raw.first_samp != 0:
            raise ValueError(
                "HBN reannotation requires first_samp=0; inspect source timing."
            )
        original_annotations.append(raw.annotations.copy())
    preprocess(ds_eoec, preprocessors)
    # These EEGPrep components never remove time. Preserve source cue times
    # across EEGLAB/MNE conversion rather than accepting sample-origin shifts.
    for recording, annotations in zip(
        ds_eoec.datasets, original_annotations, strict=True
    ):
        raw = recording.raw
        raw.set_annotations(annotations)
    # The helper replaces annotations. Preserve BAD spans for epoch rejection.
    bad_spans = [
        recording.raw.annotations[
            np.char.startswith(
                np.char.upper(recording.raw.annotations.description), "BAD"
            )
        ].copy()
        for recording in ds_eoec.datasets
    ]
    preprocess(ds_eoec, [hbn_ec_ec_reannotation()])
    for recording, bad in zip(ds_eoec.datasets, bad_spans, strict=True):
        recording.raw.set_annotations(recording.raw.annotations + bad)
    # Each derived annotation is a point marker. The stop offset extends it by
    # 256 samples (two seconds after resampling), while the matching size/stride
    # creates one full window per marker. This differs from a source annotation
    # that already carries a nonzero trial duration: do not add the same offset
    # blindly to another dataset.
    windows_ds = create_windows_from_events(
        ds_eoec,
        mapping={"eyes_closed": 0, "eyes_open": 1},
        trial_start_offset_samples=0,
        trial_stop_offset_samples=window_size_samples,
        window_size_samples=window_size_samples,
        window_stride_samples=window_size_samples,
        on_last_window="drop",
        preload=True,
        use_mne_epochs=True,
        drop_bad_windows=True,
    )
    n_win = len(windows_ds)
    print("Windows for subject:", n_win)
    all_windows.append(windows_ds)
    all_subject_ids.extend([subj] * n_win)
    valid_subjects.append(subj)


print("\nUsing valid subjects:", valid_subjects)
print("Total subjects requested:", num_subjects, " | collected:", len(valid_subjects))

# Concatenate
from braindecode.datasets import BaseConcatDataset

concat_ds = BaseConcatDataset(all_windows)
print("Total windows across valid subjects:", len(concat_ds))
Selected subjects: ['NDARAE710YWG', 'NDARAH239PGG', 'NDARAL897CYV']
╭────────────────────── EEG 2025 Competition Data Notice ──────────────────────╮
│ This notice is only for users who are participating in the EEG 2025          │
│ Competition.                                                                 │
│                                                                              │
│ EEG 2025 Competition Data Notice!                                            │
│ You are loading one of the datasets that is used in competition, but via     │
│ `EEGDashDataset`.                                                            │
│                                                                              │
│ IMPORTANT:                                                                   │
│ If you download data from `EEGDashDataset`, it is NOT identical to the       │
│ official                                                                     │
│ competition data, which is accessed via `EEGChallengeDataset`. The           │
│ competition data has been downsampled and filtered.                          │
│                                                                              │
│ If you are participating in the competition,                                 │
│ you must use the `EEGChallengeDataset` object to ensure consistency.         │
│                                                                              │
│ If you are not participating in the competition, you can ignore this         │
│ message.                                                                     │
╰─────────────────────────── Source: EEGDashDataset ───────────────────────────╯
[10/16/26 16:00:31] INFO     Auto-corrected misrouted             dataset.py:562
                             storage.base for dataset on005514:
                             s3://nemar/on005514 ->
                             s3://openneuro.org/ds005514
Reading 0 ... 180962  =      0.000 ...   361.924 secs...
/tmp/tmpi76agg73.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
[10/16/26 16:00:32] WARNING  EEGPrep event count       eegprep_preprocess.py:123
                             changed during
                             RemoveDCOffset processing
                             (14 annotated events, 13
                             non-boundary events);
                             restoring durations in
                             order for the overlapping
                             subset only.
                    WARNING  EEGPrep event count       eegprep_preprocess.py:123
                             changed during
                             RemoveDCOffset processing
                             (14 annotated events, 13
                             non-boundary events);
                             restoring durations in
                             order for the overlapping
                             subset only.
/tmp/tmpj2cg2mtg.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
/tmp/tmpgvbh65ui.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
Filtering raw data in 1 contiguous segment
Setting up low-pass filter at 55 Hz

FIR filter parameters
---------------------
Designing a one-pass, zero-phase, non-causal lowpass filter:
- Windowed time-domain design (firwin) method
- Hamming window with 0.0194 passband ripple and 53 dB stopband attenuation
- Upper passband edge: 55.00 Hz
- Upper transition bandwidth: 9.00 Hz (-6 dB cutoff frequency: 59.50 Hz)
- Filter length: 47 samples (0.367 s)

Used Annotations descriptions: ['boundary', 'break cnt', 'instructed_toCloseEyes', 'instructed_toOpenEyes', 'resting_start']
                    INFO     Original events found with ids: preprocessing.py:66
                             {'boundary': 1, 'break cnt': 2,
                             'instructed_toCloseEyes': 3,
                             'instructed_toOpenEyes': 4,
                             'resting_start': 5}
/home/runner/work/EEGDash/EEGDash/eegdash/hbn/preprocessing.py:103: RuntimeWarning: Omitted 7 annotation(s) that were outside data range.
  raw.set_annotations(annot_from_events)
/home/runner/work/EEGDash/EEGDash/.venv/lib/python3.12/site-packages/braindecode/preprocessing/windowers.py:434: UserWarning: Drop bad windows only has an effect if mne epochs are created, and this argument may be removed in the future.
  warnings.warn(
Windows for subject: 70
╭────────────────────── EEG 2025 Competition Data Notice ──────────────────────╮
│ This notice is only for users who are participating in the EEG 2025          │
│ Competition.                                                                 │
│                                                                              │
│ EEG 2025 Competition Data Notice!                                            │
│ You are loading one of the datasets that is used in competition, but via     │
│ `EEGDashDataset`.                                                            │
│                                                                              │
│ IMPORTANT:                                                                   │
│ If you download data from `EEGDashDataset`, it is NOT identical to the       │
│ official                                                                     │
│ competition data, which is accessed via `EEGChallengeDataset`. The           │
│ competition data has been downsampled and filtered.                          │
│                                                                              │
│ If you are participating in the competition,                                 │
│ you must use the `EEGChallengeDataset` object to ensure consistency.         │
│                                                                              │
│ If you are not participating in the competition, you can ignore this         │
│ message.                                                                     │
╰─────────────────────────── Source: EEGDashDataset ───────────────────────────╯
                    INFO     Auto-corrected misrouted             dataset.py:562
                             storage.base for dataset on005514:
                             s3://nemar/on005514 ->
                             s3://openneuro.org/ds005514
Reading 0 ... 180116  =      0.000 ...   360.232 secs...
/tmp/tmp60fik5m6.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
[10/16/26 16:00:33] WARNING  EEGPrep event count       eegprep_preprocess.py:123
                             changed during
                             RemoveDCOffset processing
                             (14 annotated events, 13
                             non-boundary events);
                             restoring durations in
                             order for the overlapping
                             subset only.
                    WARNING  EEGPrep event count       eegprep_preprocess.py:123
                             changed during
                             RemoveDCOffset processing
                             (14 annotated events, 13
                             non-boundary events);
                             restoring durations in
                             order for the overlapping
                             subset only.
/tmp/tmpm73qiqzo.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
/tmp/tmpnpylaqv7.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
Filtering raw data in 1 contiguous segment
Setting up low-pass filter at 55 Hz

FIR filter parameters
---------------------
Designing a one-pass, zero-phase, non-causal lowpass filter:
- Windowed time-domain design (firwin) method
- Hamming window with 0.0194 passband ripple and 53 dB stopband attenuation
- Upper passband edge: 55.00 Hz
- Upper transition bandwidth: 9.00 Hz (-6 dB cutoff frequency: 59.50 Hz)
- Filter length: 47 samples (0.367 s)

Used Annotations descriptions: ['boundary', 'break cnt', 'instructed_toCloseEyes', 'instructed_toOpenEyes', 'resting_start']
                    INFO     Original events found with ids: preprocessing.py:66
                             {'boundary': 1, 'break cnt': 2,
                             'instructed_toCloseEyes': 3,
                             'instructed_toOpenEyes': 4,
                             'resting_start': 5}
/home/runner/work/EEGDash/EEGDash/eegdash/hbn/preprocessing.py:103: RuntimeWarning: Omitted 7 annotation(s) that were outside data range.
  raw.set_annotations(annot_from_events)
/home/runner/work/EEGDash/EEGDash/.venv/lib/python3.12/site-packages/braindecode/preprocessing/windowers.py:434: UserWarning: Drop bad windows only has an effect if mne epochs are created, and this argument may be removed in the future.
  warnings.warn(
Windows for subject: 70
╭────────────────────── EEG 2025 Competition Data Notice ──────────────────────╮
│ This notice is only for users who are participating in the EEG 2025          │
│ Competition.                                                                 │
│                                                                              │
│ EEG 2025 Competition Data Notice!                                            │
│ You are loading one of the datasets that is used in competition, but via     │
│ `EEGDashDataset`.                                                            │
│                                                                              │
│ IMPORTANT:                                                                   │
│ If you download data from `EEGDashDataset`, it is NOT identical to the       │
│ official                                                                     │
│ competition data, which is accessed via `EEGChallengeDataset`. The           │
│ competition data has been downsampled and filtered.                          │
│                                                                              │
│ If you are participating in the competition,                                 │
│ you must use the `EEGChallengeDataset` object to ensure consistency.         │
│                                                                              │
│ If you are not participating in the competition, you can ignore this         │
│ message.                                                                     │
╰─────────────────────────── Source: EEGDashDataset ───────────────────────────╯
                    INFO     Auto-corrected misrouted             dataset.py:562
                             storage.base for dataset on005514:
                             s3://nemar/on005514 ->
                             s3://openneuro.org/ds005514
Reading 0 ... 174811  =      0.000 ...   349.622 secs...
/tmp/tmpd960a_i0.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
[10/16/26 16:00:34] WARNING  EEGPrep event count       eegprep_preprocess.py:123
                             changed during
                             RemoveDCOffset processing
                             (14 annotated events, 13
                             non-boundary events);
                             restoring durations in
                             order for the overlapping
                             subset only.
                    WARNING  EEGPrep event count       eegprep_preprocess.py:123
                             changed during
                             RemoveDCOffset processing
                             (14 annotated events, 13
                             non-boundary events);
                             restoring durations in
                             order for the overlapping
                             subset only.
/tmp/tmpst7dytl7.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
/tmp/tmp5wnu2xse.set
Field 'subject' is missing from the EEG dictionnary, adding it.
Field 'group' is missing from the EEG dictionnary, adding it.
Field 'condition' is missing from the EEG dictionnary, adding it.
Field 'session' is missing from the EEG dictionnary, adding it.
Field 'comments' is missing from the EEG dictionnary, adding it.
Field 'times' is missing from the EEG dictionnary, adding it.
Field 'icaact' is missing from the EEG dictionnary, adding it.
Field 'icachansind' is missing from the EEG dictionnary, adding it.
Field 'urchanlocs' is missing from the EEG dictionnary, adding it.
Field 'urevent' is missing from the EEG dictionnary, adding it.
Field 'eventdescription' is missing from the EEG dictionnary, adding it.
Field 'epoch' is missing from the EEG dictionnary, adding it.
Field 'epochdescription' is missing from the EEG dictionnary, adding it.
Field 'stats' is missing from the EEG dictionnary, adding it.
Field 'specdata' is missing from the EEG dictionnary, adding it.
Field 'specicaact' is missing from the EEG dictionnary, adding it.
Field 'splinefile' is missing from the EEG dictionnary, adding it.
Field 'icasplinefile' is missing from the EEG dictionnary, adding it.
Field 'dipfit' is missing from the EEG dictionnary, adding it.
Field 'history' is missing from the EEG dictionnary, adding it.
Field 'saved' is missing from the EEG dictionnary, adding it.
Field 'etc' is missing from the EEG dictionnary, adding it.
Field 'datfile' is missing from the EEG dictionnary, adding it.
Field 'run' is missing from the EEG dictionnary, adding it.
Field 'roi' is missing from the EEG dictionnary, adding it.
Filtering raw data in 1 contiguous segment
Setting up low-pass filter at 55 Hz

FIR filter parameters
---------------------
Designing a one-pass, zero-phase, non-causal lowpass filter:
- Windowed time-domain design (firwin) method
- Hamming window with 0.0194 passband ripple and 53 dB stopband attenuation
- Upper passband edge: 55.00 Hz
- Upper transition bandwidth: 9.00 Hz (-6 dB cutoff frequency: 59.50 Hz)
- Filter length: 47 samples (0.367 s)

Used Annotations descriptions: ['boundary', 'break cnt', 'instructed_toCloseEyes', 'instructed_toOpenEyes', 'resting_start']
                    INFO     Original events found with ids: preprocessing.py:66
                             {'boundary': 1, 'break cnt': 2,
                             'instructed_toCloseEyes': 3,
                             'instructed_toOpenEyes': 4,
                             'resting_start': 5}
/home/runner/work/EEGDash/EEGDash/eegdash/hbn/preprocessing.py:103: RuntimeWarning: Omitted 7 annotation(s) that were outside data range.
  raw.set_annotations(annot_from_events)
/home/runner/work/EEGDash/EEGDash/.venv/lib/python3.12/site-packages/braindecode/preprocessing/windowers.py:434: UserWarning: Drop bad windows only has an effect if mne epochs are created, and this argument may be removed in the future.
  warnings.warn(
Windows for subject: 70

Using valid subjects: ['NDARAE710YWG', 'NDARAH239PGG', 'NDARAL897CYV']
Total subjects requested: 3  | collected: 3
Total windows across valid subjects: 210
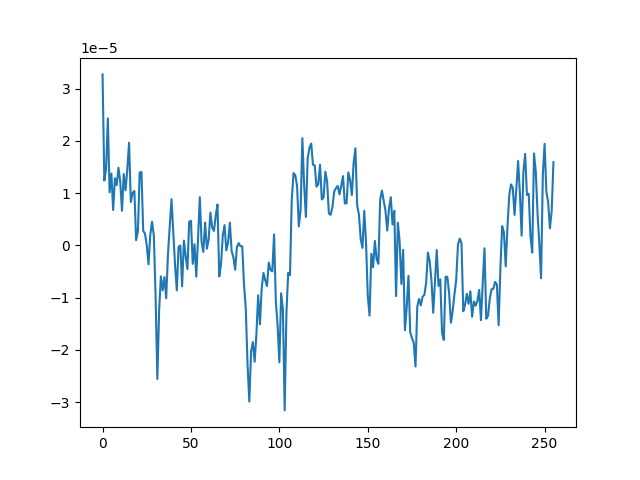
4. Inspect one recorded window without a display server#
A labelled excerpt checks waveform extraction, not class separability.
import matplotlib.pyplot as plt

signal, label, _ = concat_ds[0]
fig, ax = plt.subplots(figsize=(8, 3), layout="constrained")
ax.plot(np.arange(signal.shape[-1]) / 128, signal[0] * 1e6)
ax.set(
    xlabel="Time from window start (s)",
    ylabel=f"{channels[0]} (µV)",
    title=f"{valid_subjects[0]} · instructed {'closed' if label == 0 else 'open'}",
)
fig.savefig(run_dir / "sample_epoch.png", dpi=150)
5. Keep the test participant outside training#
Shuffle participant IDs once, not windows across participants. The default seed assigns one person to test and two to train; all windows from each person stay together. Multiple windows from the same instructed block are correlated, so window count is not the number of independent participants.
rng = np.random.RandomState(random_state)
subjects_shuffled = valid_subjects.copy()
rng.shuffle(subjects_shuffled)

test_subjects = set(subjects_shuffled[:num_test_subjects])
train_subjects = set(subjects_shuffled[num_test_subjects:])
print("\nTrain subjects:", sorted(train_subjects))
print("Test subjects :", sorted(test_subjects))

indices = np.arange(len(concat_ds))
subj_arr = np.array(all_subject_ids)

train_indices = indices[np.isin(subj_arr, list(train_subjects))]
test_indices = indices[np.isin(subj_arr, list(test_subjects))]

print("Train windows:", len(train_indices), "Test windows:", len(test_indices))
Train subjects: ['NDARAH239PGG', 'NDARAL897CYV']
Test subjects : ['NDARAE710YWG']
Train windows: 140 Test windows: 70
6. Build training and test batches#
Each input has axes (windows, 24 channels, 256 samples) and starts in volts. The default cohort has 140 training and 70 test windows. Labels are integer class indices: zero for eyes-closed, one for eyes-open. A label mean of 0.5 means equal counts, not an accuracy result. Only training batches shuffle. Materializing arrays is practical here; a much larger cohort should use indexed datasets/lazy loaders rather than duplicating every window in RAM.
torch.manual_seed(random_state)
np.random.seed(random_state)

X_train = torch.FloatTensor(np.array([concat_ds[i][0] for i in train_indices]))
X_test = torch.FloatTensor(np.array([concat_ds[i][0] for i in test_indices]))
y_train = torch.LongTensor(np.array([concat_ds[i][1] for i in train_indices]))
y_test = torch.LongTensor(np.array([concat_ds[i][1] for i in test_indices]))

from torch.utils.data import DataLoader, TensorDataset

dataset_train = TensorDataset(X_train, y_train)
dataset_test = TensorDataset(X_test, y_test)

train_loader = DataLoader(dataset_train, batch_size=batch_size, shuffle=True)
test_loader = DataLoader(dataset_test, batch_size=batch_size, shuffle=False)

print(
    f"X_train {X_train.shape} | Train batches: {len(train_loader)} | Test batches: {len(test_loader)}"
)
print(
    f"Label balance train: {float(y_train.float().mean()):.2f} | test: {float(y_test.float().mean()):.2f}"
)
X_train torch.Size([140, 24, 256]) | Train batches: 5 | Test batches: 3
Label balance train: 0.50 | test: 0.50
7. Match the neural model to the window contract#
ShallowFBCSPNet combines temporal/spatial filtering with pooled power-like features. The constructor specifies 24 channels, two output scores and 256 time samples. final_conv_length=”auto” derives the final temporal kernel from that input length; changing windows requires changing n_times.
from torch.nn import functional as F
from braindecode.models import ShallowFBCSPNet

model = torch.nn.Sequential(
    torch.nn.LayerNorm(256, eps=1e-14, elementwise_affine=False),
    ShallowFBCSPNet(24, 2, n_times=256, final_conv_length="auto"),
)
8. Train for a fixed schedule and reserve the final evaluation#
Adamax uses a fixed learning rate of 0.002 and weight decay of 0.001. Six epochs are an inexpensive workflow check, not a tuned convergence claim. Changing these choices after reading test accuracy uses the test person for selection; instead reserve validation people inside the training cohort.
optimizer = torch.optim.Adamax(model.parameters(), lr=0.002, weight_decay=0.001)

device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
model = model.to(device=device)

print("Using epochs =", epochs, "| device =", device, "| batch_size =", batch_size)
Using epochs = 6 | device = cpu | batch_size = 32
Normalization is per window and channel, along the time axis. The model therefore consumes dimensionless standardized signals. Native LayerNorm divides by sqrt(population variance + 1e-14 V²), with no learned affine parameters. This replaces a custom normalization helper and keeps division finite for nearly constant channels. This transform does not estimate a shared mean or variance across participants, so applying it to a test window does not expose other test windows to the trained model.
Each forward pass produces two class scores per window. Cross-entropy compares them with the observed integer target; backpropagation updates only the training model. model.train() enables training behavior such as dropout and BatchNorm updates. The final model.eval() and no_grad() disable those updates and gradient tracking for the reserved participant.
history = []
for e in range(epochs):
    model.train()
    correct_train = 0.0
    total_loss = 0.0
    for x, y in train_loader:
        scores = model(x.to(device=device, dtype=torch.float32))
        y = y.to(device=device, dtype=torch.long)

        loss = F.cross_entropy(scores, y)
        if not torch.isfinite(loss):
            raise ValueError(
                "Nonfinite training loss; this run cannot be marked successful."
            )
        total_loss += loss.item() * len(y)
        optimizer.zero_grad()
        loss.backward()
        optimizer.step()

        preds = scores.argmax(dim=1)
        correct_train += (preds == y).sum().item()

    history.append(
        {
            "epoch": e + 1,
            "training loss": total_loss / len(dataset_train),
            "training accuracy": correct_train / len(dataset_train),
        }
    )
    print(history[-1])

# Evaluate the held-out subjects once after the fixed training schedule.
model.eval()
correct_test = 0
with torch.no_grad():
    for x, y in test_loader:
        scores = model(x.to(device=device, dtype=torch.float32))
        if not torch.isfinite(scores).all():
            raise ValueError(
                "Nonfinite held-out scores; this run cannot be marked successful."
            )
        correct_test += (scores.argmax(dim=1).cpu() == y).sum().item()
test_accuracy = correct_test / len(dataset_test)
metrics = {
    "held-out window accuracy": test_accuracy,
    "train subjects": sorted(train_subjects),
    "test subjects": sorted(test_subjects),
    "seed": random_state,
    "epochs": epochs,
    "train windows": len(dataset_train),
    "test windows": len(dataset_test),
    "train participants": len(train_subjects),
    "test participants": len(test_subjects),
    "total seconds": perf_counter() - run_start,
    "device": str(device),
    "torch threads": torch.get_num_threads(),
}
pd.DataFrame(history).to_csv(run_dir / "training.csv", index=False)
(run_dir / "metrics.json").write_text(json.dumps(metrics, indent=2))
# A completion marker is written only after all requested artifacts succeed.
(run_dir / "_SUCCESS").write_text("Completed fixed-budget EO/EC workload\n")
pd.DataFrame([metrics])
{'epoch': 1, 'training loss': 1.0501706293651036, 'training accuracy': 0.5928571428571429}
{'epoch': 2, 'training loss': 0.6818246279444014, 'training accuracy': 0.7}
{'epoch': 3, 'training loss': 0.6737179211207799, 'training accuracy': 0.7}
{'epoch': 4, 'training loss': 0.5476626787866865, 'training accuracy': 0.7214285714285714}
{'epoch': 5, 'training loss': 0.4701142191886902, 'training accuracy': 0.7642857142857142}
{'epoch': 6, 'training loss': 0.39829241377966745, 'training accuracy': 0.8285714285714286}
9. Interpret the job outputs and plan validation#
Training accuracy is counted during parameter updates, so it is not a separate fixed-model evaluation. Final accuracy is the fraction of the reserved participant’s windows classified correctly. The default test labels are balanced; check the printed balance when changing the cohort before using 0.5 as a chance reference. Seventy windows from one person do not provide seventy independent estimates of population generalization.
If the training score rises while the held-out score stays low, investigate a validation split of additional training people before increasing epochs. For a research result, repeat subject-disjoint outer folds and report each participant’s score. Save metrics, logs and sample_epoch.png to persistent storage before job scratch is removed; a successful Slurm exit alone is not evidence that the classifier generalizes.
Total running time of the script: (0 minutes 4.663 seconds)