Note
Go to the end to download the full example code or to run this example in your browser via Binder.
Does resting-state pretraining transfer to reaction time?#
Load three R5 mini participants and run 1 of contrast-change detection. Predict stimulus-to-response time in seconds from the preceding two seconds of EEG. The split holds out a complete participant; selected samples end at stimulus onset. Pretrain an EEGNet on observed eyes-open/closed cues from the two training participants, then adapt its encoder to reaction-time regression. Compare with an identically shaped network trained from scratch. No recording from the test participant enters either training stage. Fixed two-epoch budgets illustrate the operations; this is not evidence for general transfer gains.
Before you start#
Use an installed EEGDash environment with Braindecode, MNE, NumPy,
scikit-learn and Matplotlib; this script runs on CPU. Keep a persistent
EEGDASH_CACHE_DIR: the three contrast-change run-1 recordings are downloaded
in full on first access even though each example uses short windows. The
transfer version also needs two resting-state recordings. Both tasks use the
challenge’s 100 Hz, 0.5–50 Hz filtered derivatives.
Reaction time is a continuous observed latency, not a fast/slow category. The window ends at the stimulus anchor. This excludes poststimulus samples from the selected interval, but does not establish a causal online pipeline: the source release has already been filtered and its preprocessing must be audited separately before claiming real-time prediction.
import os
from pathlib import Path

import matplotlib.pyplot as plt
import numpy as np
from braindecode.preprocessing import create_windows_from_events
import copy
import torch
from braindecode.models import EEGNet
from braindecode import EEGClassifier, EEGRegressor
from sklearn.metrics import mean_absolute_error

from eegdash import EEGChallengeDataset
from eegdash.hbn.windows import (
    annotate_trials_with_target,
    add_aux_anchors,
    add_extras_columns,
)
Load the named participants and observed events#
The explicit run filter prevents a subject query from pulling all three contrast-change runs. The first two subject IDs will train the model; the third is reserved for evaluation. The subject-coverage assertion catches a missing recording instead of silently changing that design.
annotate_trials_with_target reads the recording’s event sidecar and pairs
contrast trials with actual stimulus and response times. Trials without the
required events do not supply an observed latency. add_aux_anchors places
annotations at those actual stimulus times; it does not create response labels.
Inspect the printed annotation names and 100 Hz rate before windowing.
subjects = ["NDARDC843HHM", "NDAREC480KFA", "NDARAP785CTE"]
cache = Path(os.environ.get("EEGDASH_CACHE_DIR", "~/.eegdash_cache")).expanduser()
dataset = EEGChallengeDataset(
    release="R5",
    mini=True,
    task="contrastChangeDetection",
    subject=subjects,
    run="1",
    cache_dir=cache,
)
print(dataset.description.to_string(index=False))
assert set(dataset.description.subject) == set(subjects)
for recording in dataset.datasets:
    raw = recording.raw
    raw.pick("eeg")
    print(
        recording.description.subject,
        raw.ch_names,
        raw.info["sfreq"],
        np.unique(raw.annotations.description),
    )
    assert raw.info["sfreq"] == 100
    annotate_trials_with_target(raw, target_field="rt_from_stimulus")
    add_aux_anchors(raw)
╭────────────────────── EEG 2025 Competition Data Notice ──────────────────────╮
│ This object loads the HBN dataset that has been preprocessed for the EEG     │
│ Challenge:                                                                   │
│   * Downsampled from 500Hz to 100Hz                                          │
│   * Bandpass filtered (0.5-50 Hz)                                            │
│                                                                              │
│ For full preprocessing applied for competition details, see:                 │
│   https://github.com/eeg2025/downsample-datasets                             │
│                                                                              │
│ The HBN dataset have some preprocessing applied by the HBN team:             │
│   * Re-reference (Cz Channel)                                                │
│                                                                              │
│ IMPORTANT: The data accessed via `EEGChallengeDataset` is NOT identical to   │
│ what you get from EEGDashDataset directly.                                   │
│ If you are participating in the competition, always use                      │
│ `EEGChallengeDataset` to ensure consistency with the challenge data.         │
╰──────────────────────── Source: EEGChallengeDataset ─────────────────────────╯
[09/16/26 20:48:37] INFO     Auto-corrected misrouted             dataset.py:561
                             storage.base for dataset
                             EEG2025r5mini: None ->
                             s3://nemar/EEG2025r5mini
     subject run                    task     age sex release_number  ehq_total commercial_use full_pheno  p_factor  attention  internalizing  externalizing restingstate despicableme funwithfractals thepresent diaryofawimpykid contrastchangedetection_1 contrastchangedetection_2 contrastchangedetection_3 surroundsupp_1 surroundsupp_2 seqlearning6target seqlearning8target symbolsearch session gender
NDARAP785CTE   1 contrastChangeDetection  8.7157   M             R5     100.05            Yes         No    -0.960      1.556         -0.623         -0.685    available    available       available  available        available                 available                 available                 available      available      available        unavailable          available    available    None   None
NDARDC843HHM   1 contrastChangeDetection  9.7593   M             R5     -40.02            Yes         No    -0.696      1.086         -1.293          0.574    available    available       available  available        available                 available                 available                 available      available      available        unavailable          available    available    None   None
NDAREC480KFA   1 contrastChangeDetection 10.4762   M             R5      -6.67            Yes        Yes    -0.834     -0.910         -1.233          1.913    available    available       available  available        available                 available                 available                 available      available      available        unavailable          available    available    None   None

Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_eeg.bdf:   0%|          | 0.00/11.3M [00:00<?, ?B/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_eeg.bdf:   0%|          | 0.00/11.3M [00:00<?, ?B/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_eeg.bdf:   9%|▉         | 1.00M/11.3M [00:00<00:02, 3.84MB/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_eeg.bdf: 100%|██████████| 11.3M/11.3M [00:00<00:00, 29.1MB/s]

Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_channels.tsv: 100%|██████████| 3.34k/3.34k [00:00<00:00, 61.0kB/s]

Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_events.tsv:   0%|          | 0.00/3.02k [00:00<?, ?B/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_events.tsv:   0%|          | 0.00/3.02k [00:00<?, ?B/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_events.tsv: 100%|██████████| 3.02k/3.02k [00:00<00:00, 69.9kB/s]

Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_eeg.json:   0%|          | 0.00/242 [00:00<?, ?B/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_eeg.json:   0%|          | 0.00/242 [00:00<?, ?B/s]
Downloading sub-NDARAP785CTE_task-contrastChangeDetection_run-1_eeg.json: 100%|██████████| 242/242 [00:00<00:00, 6.07kB/s]
NDARAP785CTE ['E1', 'E2', 'E3', 'E4', 'E5', 'E6', 'E7', 'E8', 'E9', 'E10', 'E11', 'E12', 'E13', 'E14', 'E15', 'E16', 'E17', 'E18', 'E19', 'E20', 'E21', 'E22', 'E23', 'E24', 'E25', 'E26', 'E27', 'E28', 'E29', 'E30', 'E31', 'E32', 'E33', 'E34', 'E35', 'E36', 'E37', 'E38', 'E39', 'E40', 'E41', 'E42', 'E43', 'E44', 'E45', 'E46', 'E47', 'E48', 'E49', 'E50', 'E51', 'E52', 'E53', 'E54', 'E55', 'E56', 'E57', 'E58', 'E59', 'E60', 'E61', 'E62', 'E63', 'E64', 'E65', 'E66', 'E67', 'E68', 'E69', 'E70', 'E71', 'E72', 'E73', 'E74', 'E75', 'E76', 'E77', 'E78', 'E79', 'E80', 'E81', 'E82', 'E83', 'E84', 'E85', 'E86', 'E87', 'E88', 'E89', 'E90', 'E91', 'E92', 'E93', 'E94', 'E95', 'E96', 'E97', 'E98', 'E99', 'E100', 'E101', 'E102', 'E103', 'E104', 'E105', 'E106', 'E107', 'E108', 'E109', 'E110', 'E111', 'E112', 'E113', 'E114', 'E115', 'E116', 'E117', 'E118', 'E119', 'E120', 'E121', 'E122', 'E123', 'E124', 'E125', 'E126', 'E127', 'E128', 'Cz'] 100.0 ['9999' 'break cnt' 'contrastChangeB1_start' 'contrastTrial_start'
 'left_buttonPress' 'left_target' 'right_buttonPress' 'right_target']

Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_eeg.bdf:   0%|          | 0.00/9.29M [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_eeg.bdf:   0%|          | 0.00/9.29M [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_eeg.bdf:  11%|█         | 1.00M/9.29M [00:00<00:02, 3.76MB/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_eeg.bdf: 100%|██████████| 9.29M/9.29M [00:00<00:00, 23.8MB/s]

Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_channels.tsv: 100%|██████████| 3.34k/3.34k [00:00<00:00, 77.8kB/s]

Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_events.tsv:   0%|          | 0.00/2.91k [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_events.tsv:   0%|          | 0.00/2.91k [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_events.tsv: 100%|██████████| 2.91k/2.91k [00:00<00:00, 59.7kB/s]

Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_eeg.json:   0%|          | 0.00/242 [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_eeg.json:   0%|          | 0.00/242 [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-contrastChangeDetection_run-1_eeg.json: 100%|██████████| 242/242 [00:00<00:00, 6.13kB/s]
NDARDC843HHM ['E1', 'E2', 'E3', 'E4', 'E5', 'E6', 'E7', 'E8', 'E9', 'E10', 'E11', 'E12', 'E13', 'E14', 'E15', 'E16', 'E17', 'E18', 'E19', 'E20', 'E21', 'E22', 'E23', 'E24', 'E25', 'E26', 'E27', 'E28', 'E29', 'E30', 'E31', 'E32', 'E33', 'E34', 'E35', 'E36', 'E37', 'E38', 'E39', 'E40', 'E41', 'E42', 'E43', 'E44', 'E45', 'E46', 'E47', 'E48', 'E49', 'E50', 'E51', 'E52', 'E53', 'E54', 'E55', 'E56', 'E57', 'E58', 'E59', 'E60', 'E61', 'E62', 'E63', 'E64', 'E65', 'E66', 'E67', 'E68', 'E69', 'E70', 'E71', 'E72', 'E73', 'E74', 'E75', 'E76', 'E77', 'E78', 'E79', 'E80', 'E81', 'E82', 'E83', 'E84', 'E85', 'E86', 'E87', 'E88', 'E89', 'E90', 'E91', 'E92', 'E93', 'E94', 'E95', 'E96', 'E97', 'E98', 'E99', 'E100', 'E101', 'E102', 'E103', 'E104', 'E105', 'E106', 'E107', 'E108', 'E109', 'E110', 'E111', 'E112', 'E113', 'E114', 'E115', 'E116', 'E117', 'E118', 'E119', 'E120', 'E121', 'E122', 'E123', 'E124', 'E125', 'E126', 'E127', 'E128', 'Cz'] 100.0 ['9999' 'break cnt' 'contrastChangeB1_start' 'contrastTrial_start'
 'left_buttonPress' 'left_target' 'right_buttonPress' 'right_target']

Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_eeg.bdf:   0%|          | 0.00/16.5M [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_eeg.bdf:   0%|          | 0.00/16.5M [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_eeg.bdf:   6%|▌         | 1.00M/16.5M [00:00<00:03, 4.74MB/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_eeg.bdf: 100%|██████████| 16.5M/16.5M [00:00<00:00, 47.6MB/s]

Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_channels.tsv: 100%|██████████| 3.34k/3.34k [00:00<00:00, 85.4kB/s]

Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_events.tsv:   0%|          | 0.00/2.72k [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_events.tsv:   0%|          | 0.00/2.72k [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_events.tsv: 100%|██████████| 2.72k/2.72k [00:00<00:00, 79.2kB/s]

Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_eeg.json:   0%|          | 0.00/242 [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_eeg.json:   0%|          | 0.00/242 [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-contrastChangeDetection_run-1_eeg.json: 100%|██████████| 242/242 [00:00<00:00, 6.43kB/s]
NDAREC480KFA ['E1', 'E2', 'E3', 'E4', 'E5', 'E6', 'E7', 'E8', 'E9', 'E10', 'E11', 'E12', 'E13', 'E14', 'E15', 'E16', 'E17', 'E18', 'E19', 'E20', 'E21', 'E22', 'E23', 'E24', 'E25', 'E26', 'E27', 'E28', 'E29', 'E30', 'E31', 'E32', 'E33', 'E34', 'E35', 'E36', 'E37', 'E38', 'E39', 'E40', 'E41', 'E42', 'E43', 'E44', 'E45', 'E46', 'E47', 'E48', 'E49', 'E50', 'E51', 'E52', 'E53', 'E54', 'E55', 'E56', 'E57', 'E58', 'E59', 'E60', 'E61', 'E62', 'E63', 'E64', 'E65', 'E66', 'E67', 'E68', 'E69', 'E70', 'E71', 'E72', 'E73', 'E74', 'E75', 'E76', 'E77', 'E78', 'E79', 'E80', 'E81', 'E82', 'E83', 'E84', 'E85', 'E86', 'E87', 'E88', 'E89', 'E90', 'E91', 'E92', 'E93', 'E94', 'E95', 'E96', 'E97', 'E98', 'E99', 'E100', 'E101', 'E102', 'E103', 'E104', 'E105', 'E106', 'E107', 'E108', 'E109', 'E110', 'E111', 'E112', 'E113', 'E114', 'E115', 'E116', 'E117', 'E118', 'E119', 'E120', 'E121', 'E122', 'E123', 'E124', 'E125', 'E126', 'E127', 'E128', 'Cz'] 100.0 ['9999' 'break cnt' 'contrastChangeB1_start' 'contrastTrial_start'
 'left_buttonPress' 'left_target' 'right_buttonPress' 'right_target']
Extract a two-second prestimulus predictor#
At 100 Hz, offsets -200 and 0 select the interval immediately
before the stimulus. The 200-sample size and stride produce one window for
each usable anchor. mapping={"stimulus_anchor": 0} tells the windower
which anchors to use; that zero is a selection code, not the regression target.
add_extras_columns carries the measured rt_from_stimulus into the
window metadata. Use that column for y, in seconds. A finite array with
shape (trials, EEG channels, 200) supplies predictors in volts. Positive,
finite latency assertions expose malformed event pairings; they do not require
a particular prediction error or favourable result.
windows = create_windows_from_events(
    dataset,
    mapping={"stimulus_anchor": 0},
    trial_start_offset_samples=-200,
    trial_stop_offset_samples=0,
    window_size_samples=200,
    window_stride_samples=200,
    preload=True,
)
windows = add_extras_columns(
    windows,
    dataset,
    desc="stimulus_anchor",
    keys=("target", "rt_from_stimulus", "stimulus_onset"),
)
metadata = windows.get_metadata().reset_index(drop=True)
X = np.stack([windows[i][0] for i in range(len(windows))])
y = metadata.rt_from_stimulus.to_numpy(dtype=float)
assert np.isfinite(X).all() and np.isfinite(y).all() and (y > 0).all()
train = metadata.subject.isin(subjects[:2]).to_numpy()
test = metadata.subject.eq(subjects[2]).to_numpy()
assert train.any() and test.any()
assert set(metadata.subject[train]).isdisjoint(metadata.subject[test])
# Fixed microvolt conversion does not estimate a transform on held-out data.
X = X.astype("float32") * 1e6
/home/runner/work/EEGDash/EEGDash/.venv/lib/python3.12/site-packages/braindecode/preprocessing/windowers.py:889: UserWarning: Dropping extra columns that conflict with windowing metadata: {'target'}
  warnings.warn(
/home/runner/work/EEGDash/EEGDash/.venv/lib/python3.12/site-packages/braindecode/preprocessing/windowers.py:889: UserWarning: Dropping extra columns that conflict with windowing metadata: {'target'}
  warnings.warn(
/home/runner/work/EEGDash/EEGDash/.venv/lib/python3.12/site-packages/braindecode/preprocessing/windowers.py:889: UserWarning: Dropping extra columns that conflict with windowing metadata: {'target'}
  warnings.warn(
Pretrain on an observed auxiliary task#
Only the two training participants supply resting EEG. Checking their IDs against the held-out target participant closes a common transfer-learning leak: excluding a person from fine-tuning is insufficient if their recording was already used during pretraining.
The source labels encode instructions to open (0) or close (1) the eyes. The
one-second offset moves the two-second window away from the instruction onset;
these labels reflect the protocol, not an independent measurement of eye
position. This is supervised auxiliary-task pretraining, not self-supervision.
Both source and target arrays use the identical channel order and 200-sample
length. Multiplying volts by 1e6 gives microvolts without fitting any
statistics on held-out participants.
source = EEGChallengeDataset(
    release="R5", mini=True, task="RestingState", subject=subjects[:2], cache_dir=cache
)
assert set(source.description.subject).isdisjoint(metadata.subject[test])
for recording in source.datasets:
    recording.raw.pick("eeg")
    assert recording.raw.ch_names == dataset.datasets[0].raw.ch_names
source_windows = create_windows_from_events(
    source,
    mapping={"instructed_toOpenEyes": 0, "instructed_toCloseEyes": 1},
    trial_start_offset_samples=100,
    trial_stop_offset_samples=300,
    window_size_samples=200,
    window_stride_samples=200,
    preload=True,
)
Xs = (
    np.stack([source_windows[i][0] for i in range(len(source_windows))]).astype(
        "float32"
    )
    * 1e6
)
ys = np.asarray([source_windows[i][1] for i in range(len(source_windows))])
assert np.isfinite(Xs).all() and set(ys) == {0, 1}
print(
    "Resting-state windows:",
    Xs.shape,
    "real eye-state counts:",
    np.unique(ys, return_counts=True),
)
torch.manual_seed(71)
torch.set_num_threads(2)
╭────────────────────── EEG 2025 Competition Data Notice ──────────────────────╮
│ This object loads the HBN dataset that has been preprocessed for the EEG     │
│ Challenge:                                                                   │
│   * Downsampled from 500Hz to 100Hz                                          │
│   * Bandpass filtered (0.5-50 Hz)                                            │
│                                                                              │
│ For full preprocessing applied for competition details, see:                 │
│   https://github.com/eeg2025/downsample-datasets                             │
│                                                                              │
│ The HBN dataset have some preprocessing applied by the HBN team:             │
│   * Re-reference (Cz Channel)                                                │
│                                                                              │
│ IMPORTANT: The data accessed via `EEGChallengeDataset` is NOT identical to   │
│ what you get from EEGDashDataset directly.                                   │
│ If you are participating in the competition, always use                      │
│ `EEGChallengeDataset` to ensure consistency with the challenge data.         │
╰──────────────────────── Source: EEGChallengeDataset ─────────────────────────╯
[09/16/26 20:48:40] INFO     Auto-corrected misrouted             dataset.py:561
                             storage.base for dataset
                             EEG2025r5mini: None ->
                             s3://nemar/EEG2025r5mini

Downloading sub-NDARDC843HHM_task-RestingState_eeg.bdf:   0%|          | 0.00/13.5M [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-RestingState_eeg.bdf:   0%|          | 0.00/13.5M [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-RestingState_eeg.bdf:  15%|█▍        | 2.00M/13.5M [00:00<00:01, 9.31MB/s]
Downloading sub-NDARDC843HHM_task-RestingState_eeg.bdf: 100%|██████████| 13.5M/13.5M [00:00<00:00, 45.6MB/s]

Downloading sub-NDARDC843HHM_task-RestingState_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-RestingState_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-RestingState_channels.tsv: 100%|██████████| 3.34k/3.34k [00:00<00:00, 70.3kB/s]

Downloading sub-NDARDC843HHM_task-RestingState_events.tsv:   0%|          | 0.00/519 [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-RestingState_events.tsv:   0%|          | 0.00/519 [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-RestingState_events.tsv: 100%|██████████| 519/519 [00:00<00:00, 13.1kB/s]

Downloading sub-NDARDC843HHM_task-RestingState_eeg.json:   0%|          | 0.00/231 [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-RestingState_eeg.json:   0%|          | 0.00/231 [00:00<?, ?B/s]
Downloading sub-NDARDC843HHM_task-RestingState_eeg.json: 100%|██████████| 231/231 [00:00<00:00, 6.02kB/s]

Downloading sub-NDAREC480KFA_task-RestingState_eeg.bdf:   0%|          | 0.00/13.9M [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-RestingState_eeg.bdf:   0%|          | 0.00/13.9M [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-RestingState_eeg.bdf:   7%|▋         | 1.00M/13.9M [00:00<00:03, 4.22MB/s]
Downloading sub-NDAREC480KFA_task-RestingState_eeg.bdf: 100%|██████████| 13.9M/13.9M [00:00<00:00, 38.5MB/s]

Downloading sub-NDAREC480KFA_task-RestingState_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-RestingState_channels.tsv:   0%|          | 0.00/3.34k [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-RestingState_channels.tsv: 100%|██████████| 3.34k/3.34k [00:00<00:00, 93.1kB/s]

Downloading sub-NDAREC480KFA_task-RestingState_events.tsv:   0%|          | 0.00/527 [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-RestingState_events.tsv:   0%|          | 0.00/527 [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-RestingState_events.tsv: 100%|██████████| 527/527 [00:00<00:00, 13.9kB/s]

Downloading sub-NDAREC480KFA_task-RestingState_eeg.json:   0%|          | 0.00/231 [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-RestingState_eeg.json:   0%|          | 0.00/231 [00:00<?, ?B/s]
Downloading sub-NDAREC480KFA_task-RestingState_eeg.json: 100%|██████████| 231/231 [00:00<00:00, 6.37kB/s]
Resting-state windows: (22, 129, 200) real eye-state counts: (array([0, 1]), array([12, 10]))
Train the source encoder and replace its head#
EEGNet learns temporal and spatial filters directly from the windows.
The source head returns two logits for cross-entropy; the downstream head
returns one real number for squared-error regression. Adam’s 1e-3 step size,
two epochs and 16-example batches (with a shorter final batch) are fixed teaching settings,
not hyperparameters selected for this cohort. EEGClassifier and
EEGRegressor manage batching, gradients and evaluation mode;
train_split=None prevents an additional window-level validation split.
Regression targets retain shape (trials, 1) to match the one-output head.
Target standardization uses only training latencies. Predictions are later
multiplied by that training standard deviation and shifted by the training mean
to return to seconds. Copying all state except final_layer transfers the
encoder while keeping the new one-output head. The missing-key assertion
ensures that relaxed loading has not silently discarded unrelated parameters.
Both downstream conditions begin with the same randomly initialized head.
encoder = EEGNet(n_chans=X.shape[1], n_outputs=2, n_times=200, sfreq=100)
source_trainer = EEGClassifier(
    encoder,
    criterion=torch.nn.CrossEntropyLoss,
    optimizer=torch.optim.Adam,
    lr=1e-3,
    batch_size=16,
    max_epochs=2,
    train_split=None,
    iterator_train__shuffle=False,
    classes=[0, 1],
    device="cpu",
)
source_trainer.fit(Xs, ys)
encoder = source_trainer.module_
mean, scale = y[train].mean(), y[train].std()
assert scale > 0
results = {}
initial = EEGNet(n_chans=X.shape[1], n_outputs=1, n_times=200, sfreq=100)
for regime in ["from scratch", "resting-state transfer"]:
    model = copy.deepcopy(initial)
    if regime == "resting-state transfer":
        state = {
            k: v
            for k, v in encoder.state_dict().items()
            if not k.startswith("final_layer")
        }
        missing, unexpected = model.load_state_dict(state, strict=False)
        assert not unexpected and all(k.startswith("final_layer") for k in missing)
    regressor = EEGRegressor(
        model,
        criterion=torch.nn.MSELoss,
        optimizer=torch.optim.Adam,
        lr=1e-3,
        batch_size=16,
        max_epochs=2,
        train_split=None,
        iterator_train__shuffle=False,
        device="cpu",
    )
    standardized_y = ((y[train] - mean) / scale).astype("float32")[:, None]
    regressor.fit(X[train], standardized_y)
    predicted = regressor.predict(X[test]).reshape(-1) * scale + mean
    results[regime] = mean_absolute_error(y[test], predicted)
print("Held-out reaction-time MAE (s):", results)
fig, ax = plt.subplots(figsize=(6, 4))
ax.bar(list(results), list(results.values()))
ax.set(ylabel="Held-out participant trial MAE (s)")
plt.show()
[09/16/26 20:48:42] INFO     The module passed is already    eegneuralnet.py:193
                             initialized which is not
                             recommended. Instead, you can
                             pass the module class and its
                             parameters separately.
                             For more details, see
                             https://skorch.readthedocs.io/e
                             n/stable/user/neuralnet.html#mo
                             dule
                             Skipping setting signal-related
                             parameters from data.
  epoch    train_loss     dur
-------  ------------  ------
      1        0.7056  0.0582
      2        0.6943  0.0517
[09/16/26 20:48:44] INFO     The module passed is already    eegneuralnet.py:193
                             initialized which is not
                             recommended. Instead, you can
                             pass the module class and its
                             parameters separately.
                             For more details, see
                             https://skorch.readthedocs.io/e
                             n/stable/user/neuralnet.html#mo
                             dule
                             Skipping setting signal-related
                             parameters from data.
  epoch    train_loss     dur
-------  ------------  ------
      1        1.1148  0.1037
      2        1.1118  0.1024
                    INFO     The module passed is already    eegneuralnet.py:193
                             initialized which is not
                             recommended. Instead, you can
                             pass the module class and its
                             parameters separately.
                             For more details, see
                             https://skorch.readthedocs.io/e
                             n/stable/user/neuralnet.html#mo
                             dule
                             Skipping setting signal-related
                             parameters from data.
  epoch    train_loss     dur
-------  ------------  ------
      1        1.3540  0.1033
      2        1.1786  0.1019
Held-out reaction-time MAE (s): {'from scratch': 0.793028268463976, 'resting-state transfer': 1.8783957974210803}
Interpret transfer without selecting on the test participant#
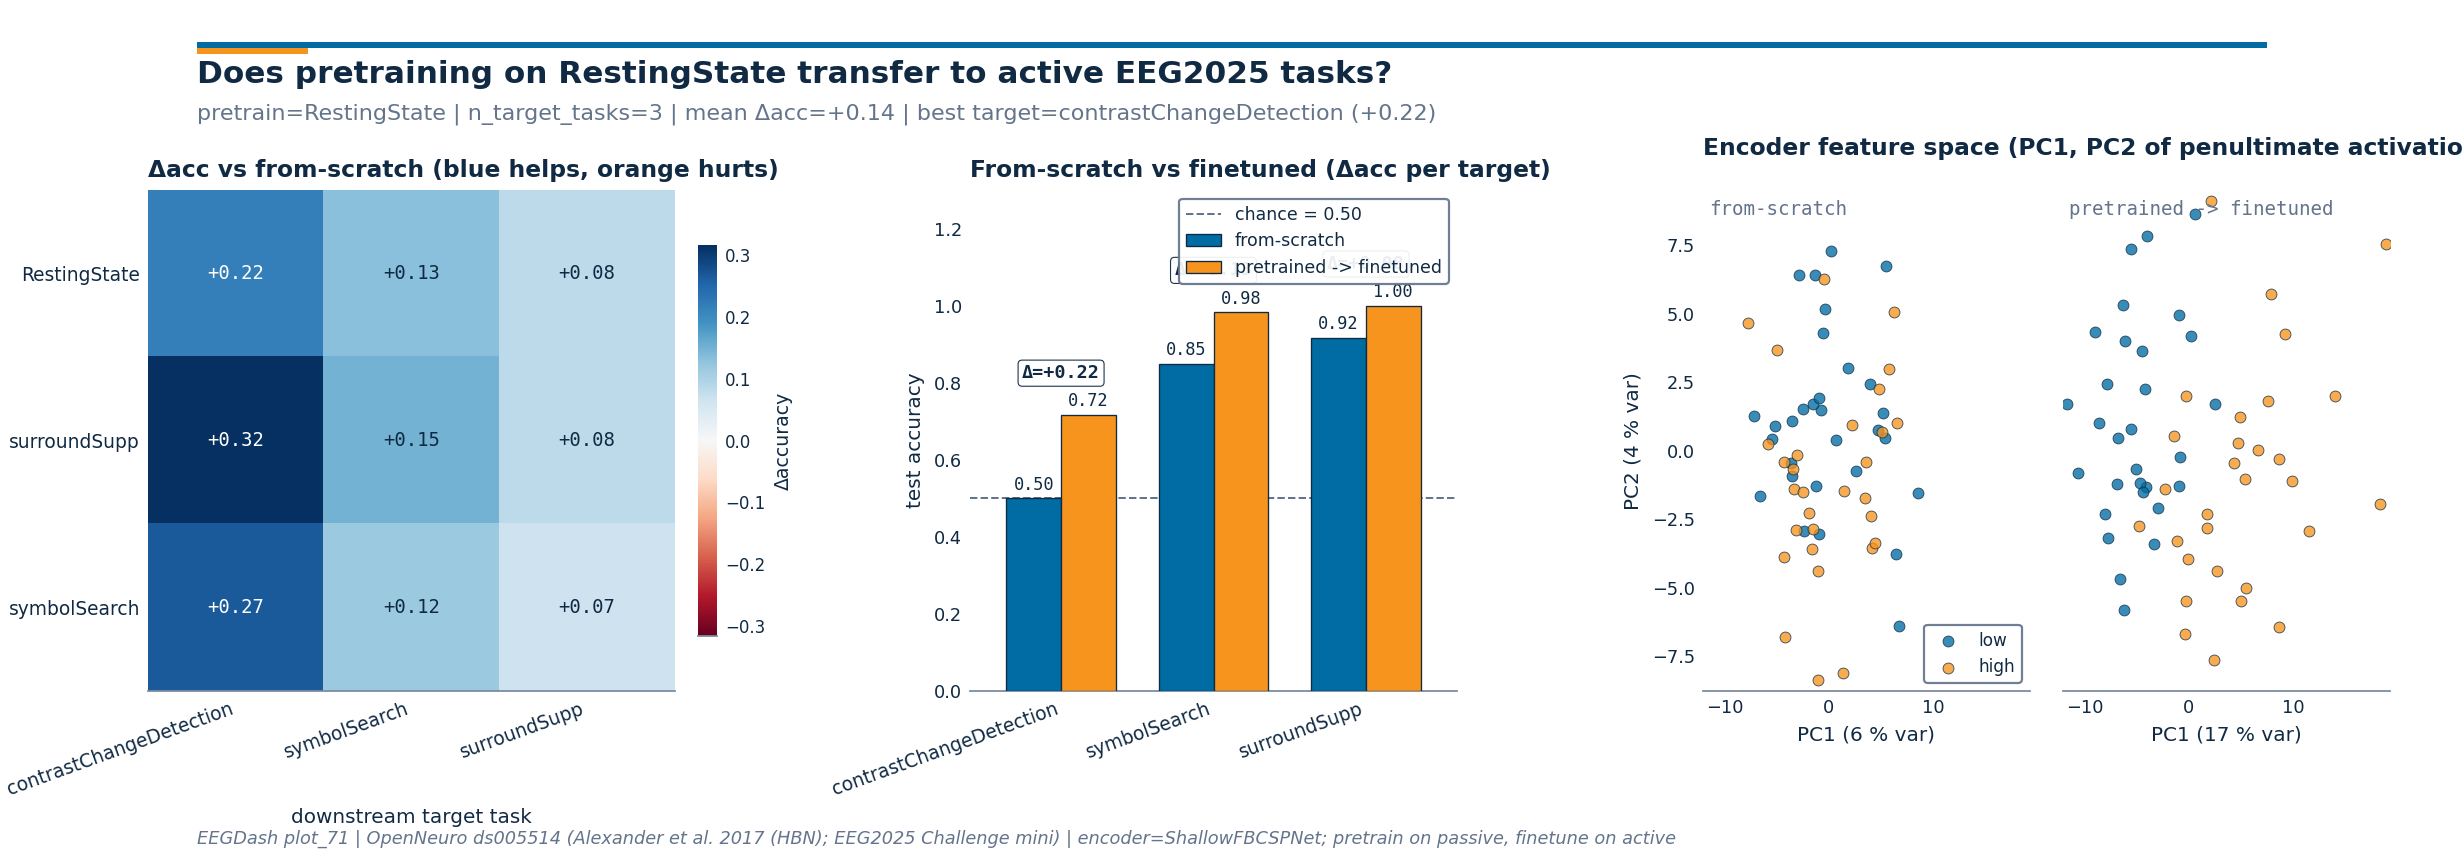
Each bar is mean absolute error over usable trials from the same held-out person; lower is better and an error of 0.1 means 100 ms on average. The transfer condition receives extra source-task training, so the comparison is not matched for total optimization steps. One subject and one initialization cannot show a reliable general transfer benefit. The plot may favour either condition.
To extend the experiment, reserve additional validation participants before either training stage. Select the epoch budget and learning rate there, then repeat the entire comparison over untouched test participants and seeds. Also compare a training-mean latency predictor and assess exclusions for missing responses. Do not tune source tasks after looking at these test bars.
Related worked examples: cross-dataset transfer and relative-positioning pretraining.
Total running time of the script: (0 minutes 7.746 seconds)